Technologies and open-source AI models: what we build with.
We rely on widely used, open technologies and open-source AI models that run locally on your hardware. This keeps your application maintainable, any experienced developer can take it over later, and you own the source code.
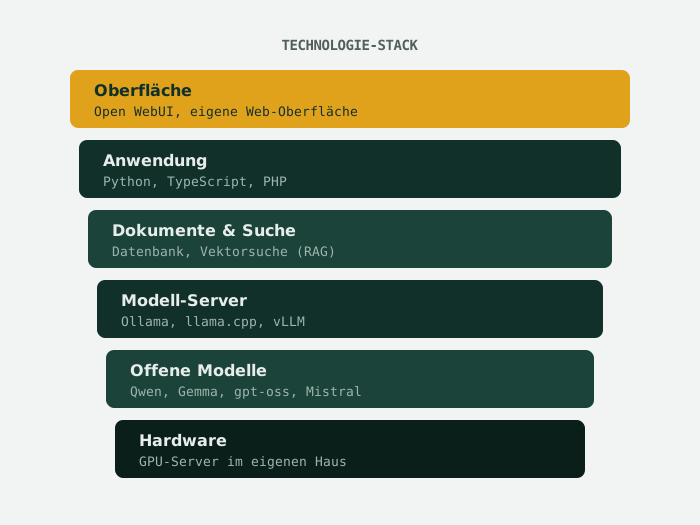
Languages and tools
Our standard is Python for servers and AI, TypeScript for the interface. We extend existing systems in their own language.
| Area | What we use |
|---|---|
| Servers and AI logic | Python (FastAPI, Django), for data processing, AI connection and interfaces |
| Interface in the browser | TypeScript with React or Next.js, responsive for desktop and smartphone |
| Existing websites | PHP, e.g. for extensions of WordPress or shop systems |
| Local AI models | Open models such as Qwen, Gemma, gpt-oss, Mistral or GLM via Ollama, llama.cpp or vLLM (list below) |
| AI models in the cloud | Interfaces of established providers, where data protection and the use case allow |
| Document search | Vector databases (e.g. pgvector, Qdrant) with source citation |
| Data | PostgreSQL, SQLite, Excel and CSV import, connection to existing databases |
| Operation | Linux servers, Docker, Git with automated deployment |
What an application from us looks like: OrderHub
Our own order management for online retail. It replaces a subscription tool, runs on an ordinary web server and is supported by an AI assistant. The demo is a copy with fictional data: no login, all actions are only simulated.
What the application does
- Orders from eBay, WooCommerce and Amazon in one list, legacy orders imported from Billbee
- PDF invoices with correct VAT (domestic, EU with VAT ID check, non-EU), batch printing, automatic sending by e-mail
- DHL shipping and return labels, tracking number sent back to the marketplace automatically
- Inbox for eBay messages and e-mail, replies from templates or from the AI assistant following fixed rules
- Change prices and stock on eBay and in the shop directly from the application
- Exports for accounting and tax (Excel, CSV), VAT report
- Notifications and queries via Telegram
What it is built with
| Language | PHP 8.1, around 10,000 lines of own code, no framework |
| Data | MySQL/MariaDB |
| Interfaces | eBay API, WooCommerce REST, Amazon SP-API, Billbee, DHL Parcel API, IMAP/SMTP, Telegram Bot API, EU VIES |
| AI integration | MCP server: the assistant reads messages, checks stock and shipping, replies according to a rulebook, special cases go to the owner |
| Libraries | dompdf (PDF), PHPMailer, SimpleXLSXGen; all bundled locally |
| Operation | Plesk server, cron every 15 minutes, deployment via Git, no subscription, no third-party fees per order |
Built in a few weeks for our own spare-parts business. The same approach applies to your application: first the workflow, then a clickable prototype, then operation.
Current local AI models (as of October 2026)
“Local” means: the model is downloaded once and then runs entirely on your own computer, without an internet connection to an AI provider. These so-called open-weight models are released free of charge by major vendors, most under licences that also permit commercial use. New versions appear every few months. We test them and swap the model when a better one is available.
| Model family | Manufacturer | Sizes (selection) | Licence | Use at our premises |
|---|---|---|---|---|
| Qwen 3.6 / 3.8 | Alibaba | 27B (compact), 35B-A3B (MoE) | Apache 2.0 | All-round standard: German, documents, programming, also understands images |
| Gemma 4 | 12B, 26B-A4B (MoE), 31B | Apache 2.0 | Very good German, images and audio as input, already runs on small hardware | |
| gpt-oss | OpenAI | 20B (3.6B active), 120B (5.1B active) | Apache 2.0 | Fast logical reasoning; 20B runs with around 16 GB of memory |
| Mistral Small 4 / Ministral 3 | Mistral AI (France) | Ministral 3–14B; Small 4 119B (MoE, approx. 6B active) | Apache 2.0 | European provider, long documents (256K context) |
| GLM-5.3-Flash | Z.ai | 320B (MoE, 18B active) | MIT | Strong agent and programming tasks, needs a larger server |
| DeepSeek V4.1-Flash | DeepSeek | 552B (MoE, 8–16B active) | MIT | Very long texts (up to 1 million tokens), only practical on large servers |
| Nemotron 3.5 | NVIDIA | 30B (MoE, approx. 3B active) | own vendor licence | Fast agents on workstations |
| Apertus / Olmo 3 | Swiss AI / Ai2 | various | open incl. training data | When traceability of the training data matters |
What the numbers mean: "27B" means 27 billion parameters. More parameters usually mean more knowledge, but also more memory required. "MoE" (Mixture of Experts) means the model is large, but only uses a small part of it ("active") for each word. Such models are fast, but still need memory for the whole model. With compression ("quantisation" to 4 bit), a 27B model fits into roughly 16–20 GB of graphics memory.
We check licences for every project. Some models from large vendors have their own licence terms with restrictions. We prefer models under Apache 2.0 or MIT.
Which hardware for which model
| Hardware class | Example | Suitable models | Who it is for |
|---|---|---|---|
| Entry level | PC with 16 GB graphics card or Mac with 32 GB | Gemma 4 12B, gpt-oss-20b, Ministral 14B | Single workstation, tests, small teams |
| Standard office use | Workstation with a 24–32 GB graphics card, e.g. RTX 4090/5090 | Qwen 27B, Gemma 4 31B, Qwen 35B-A3B | 5 to 20 users, document search, drafts |
| Advanced | 2–4 graphics cards or 128 GB unified memory (e.g. Mac Studio, AMD Ryzen AI Max, NVIDIA DGX Spark) | gpt-oss-120b, Mistral Small 4 | Many simultaneous users, more demanding tasks |
| Data centre | Server with 8 accelerators | DeepSeek V4, GLM-5.3, Kimi K3 | Usually not economical for SMEs on site |
Many tasks do not need a huge model. For document search and drafts in the office, the “Office standard” class is usually enough. We can supply hardware refurbished from our own stock. More under on-site AI servers.
The software behind the application
Running models (inference)
- Ollama: The simplest way to run a model on a single machine. Ideal for small teams and tests.
- llama.cpp: The lean foundation of many tools, also runs without a large graphics card, on Mac, Windows and Linux.
- vLLM: For servers with many simultaneous users. Distributes requests efficiently across one or more graphics cards.
Interface for employees
- Open WebUI: A browser-based chat interface, similar to ChatGPT, with user accounts, permissions and document search. Runs on your server.
- Custom interface: If the AI is to be embedded in a workflow, we build it in TypeScript with React or Next.js.
Documents, speech, search
- Text recognition and document processing: Docling and Tesseract convert PDFs, scans and Office files into searchable text.
- Dictation and meetings: Whisper (run locally via whisper.cpp or faster-whisper) transcribes German audio.
- Semantic search: Embedding models such as bge-m3 or Qwen-Embedding create the content fingerprints, stored in PostgreSQL with pgvector or in Qdrant.
Programming languages
- Python for servers, data processing and AI integration, with FastAPI for interfaces and Django for larger applications with an admin interface.
- TypeScript with React and Next.js for interfaces in the browser, on desktop and on smartphones.
- PHP, when existing websites, shops or WordPress are extended.
- SQL for databases, Bash and Docker for installation and operation on Linux servers.
Cloud models when they fit
Where no confidential data is processed or maximum performance is needed, we connect the interfaces of established providers (e.g. Anthropic, OpenAI, Google, Mistral), preferably with data centres in the EU. The application is built so that you can switch between local and cloud.
How your application is built
- RequirementsWhat should the application do, and what data is available?
- PrototypeClickable, with real sample data, within a few weeks.
- ExtensionPermissions, interfaces, tests.
- DeliveryAutomatic via Git, every change traceable.
Frequently asked questions
Why Python and TypeScript?
Python is the standard for AI and data processing, TypeScript for modern browser interfaces. Both have plenty of developers, so you are not tied to us.
Do you also write in other languages?
Yes. If your existing system is written in PHP, Java, C# or another language, we extend it in the same language instead of rebuilding everything.
Where is the source code?
In a Git repository, on request in your own GitHub or GitLab account. Every change is traceable.
Which open-source AI models do you use?
Depending on the task and hardware, for example Qwen, Gemma, gpt-oss, Mistral or GLM, run via Ollama, llama.cpp or vLLM. When new versions are released, we test them with your typical questions before switching.
Request a project
Describe your project or your existing system. We will tell you how we would implement it.
By phone: 030 417 17370
Briefly describe what you have in mind. We will get back to you with a concrete assessment.
Danziger Straße 78a
10405 Berlin
Berlin-Prenzlauer Berg